Zero Trust for AI Workloads: From Identity to GPU Infrastructure
Imagine this- it’s 10:15 a.m. Your teammate opens a chat with an internal AI assistant and asks it to gather the latest contract language about a vendor. They run a prompt, click “OK” and let the assistant analyze the documents and summarize the next steps.
The user is authenticated.
The agent has a managed identity.
The API call uses mutual Transport Layer Security (mTLS) and reaches a private inference endpoint inside the organization’s virtual network.
Are you done?
If the answer is yes, you’re missing part of the problem.
Those controls are necessary. They just aren’t sufficient anymore.
Once artificial intelligence systems introduce agents, models, retrieval systems, vector databases, and graphics processing unit (GPU)-backed infrastructure into the call chain, the Zero Trust question gets considerably bigger.
We’re no longer asking only:
Who is authenticated?
We’re asking:
Who or what is acting? What artifact is running? What data is being accessed? Where is it running? And why is that action being taken?
That’s the shift I think security architects need to make when applying Zero Trust to AI.
Zero Trust still works. The trust boundary gets bigger.
The fundamentals of Zero Trust haven’t changed.
Zero Trust Architecture (ZTA) is still about explicitly verifying access, enforcing least privilege, assuming compromise, and continuously evaluating the environment rather than trusting something simply because it sits inside a network boundary.
The difference is that AI gives us a lot more things to verify.
A traditional application might have a user, an application, a database, and a network around it. An AI workload can have a user, an agent, several tools, a retrieval service, a vector database, a model, model weights, containers, a host operating system, drivers, and GPUs.
Each of those components can become part of an attack path.
That means the policy decision has to account for more than the user’s identity and the resource they’re requesting. A Policy Decision Point (PDP)—the component that decides whether an action should be allowed—may need additional evidence about the model, workload, runtime, data, and environment.
The Policy Enforcement Point (PEP) then enforces that decision.
The basic Zero Trust model hasn’t been replaced.
We’ve expanded what the policy decision needs to know.
The identity problem: humans are only one principal
This is probably the easiest place to start.
In an AI system, the person sitting at the keyboard is only one identity in the system.
There may also be a workload running the model server, an agent acting on the user’s behalf, a retrieval service accessing documents, and tools that the agent can call.
Those identities need to be distinct.
Consider an agent that uses a developer’s long-lived credentials. If that agent is compromised, the attacker doesn’t just gain access to the agent. They potentially inherit everything that developer was allowed to do.
That’s a terrible blast radius.
Instead, agents and workloads should have their own managed identities and short-lived credentials. In Kubernetes (K8s), service accounts can be mapped to cloud workload identities so that individual workloads can be identified and authorized independently.
Microsoft Entra Workload Identity is one practical way to implement this pattern in Azure.
The important idea isn’t the Microsoft product, though.
It’s identity separation.
An agent should not become a proxy for the human who created it.
That distinction becomes even more important when agents are ephemeral, automatically created, or capable of taking actions without a human approving every individual step.
Authorization has to understand the action, not just the actor
Role-Based Access Control (RBAC) remains useful. If someone is an administrator, developer, or analyst, that role still tells us something about what they’re allowed to do.
But AI introduces situations where role alone isn’t enough.
Attribute-Based Access Control (ABAC) evaluates additional information—attributes about the identity, resource, environment, or requested action.
That’s where AI gets interesting.
Imagine an agent is authorized to use an internal ticketing system. That doesn’t necessarily mean it should be allowed to export every ticket in the system.
The authorization decision might need to consider the following:
- Which agent is making the request
- Which model is running it
- Whether that model is an approved artifact
- Whether the workload is running in an approved environment
- What data the request touches
- What operation the agent is attempting
- What the stated purpose of the action is
Instead of granting the agent broad access to the tool, the system can make an authorization decision at the point of the individual request.
That’s the direction per-call authorization takes Zero Trust.
It’s also where some of the hardest unsolved problems begin. Expressing something as simple as “this agent can reconcile invoices for this vendor but cannot export the underlying financial records” requires more than traditional role assignments.
Purpose-bound or semantic authorization is still an emerging area. The architecture should account for it without pretending the industry has already solved it.
RAG turns your data store into part of the AI’s security boundary
Retrieval-Augmented Generation (RAG) is straightforward in concept: instead of relying only on what a model learned during training, the system retrieves external information and gives that information to the model as context.
It’s incredibly useful.
It’s also a security boundary.
If the retrieval system can access sensitive documents, an attacker who compromises that system—or manipulates the documents going into it—may be able to influence what the model sees.
That makes the vector database more than an AI component.
Treat it like a sensitive database.
Use private networking, strict authentication, authorization around retrieval, and logging that tells you what information was retrieved and by whom.
Provenance matters here too.
If a response was generated using five internal documents, you should be able to determine which documents were retrieved and connect those retrieval events to the user, agent, and model involved.
That gives security teams something they desperately need with AI: a way to reconstruct what actually happened.
There’s another problem.
A malicious document can become an instruction to the model.
That’s prompt injection.
The attacker doesn’t necessarily need to compromise the database itself. They may only need to get malicious content into the retrieval corpus and wait for an AI system to consume it.
So the security boundary isn’t simply:
User → AI
It’s:
User → Agent → Retriever → Documents → Model
Every step deserves scrutiny.
Models need a software supply-chain mindset
We already know how dangerous an untrusted software artifact can be.
A model shouldn’t receive special treatment simply because it happens to contain neural-network weights instead of executable application code.
Model artifacts should have identifiable provenance, integrity protections, and deployment controls.
A Software Bill of Materials (SBOM) is an inventory of the components that make up a software artifact. Supply-chain Levels for Software Artifacts (SLSA) provides a framework for improving software build provenance and supply-chain integrity.
The exact implementation for machine-learning models is still evolving, but the underlying idea is useful: know where the model came from, what produced it, and whether the artifact being deployed is the artifact that was approved.
Cryptographically signing a model can establish origin and integrity.
It cannot establish that the model is safe.
A malicious model can be perfectly signed.
A poisoned training dataset can produce a perfectly signed model.
A legitimate model can still behave badly when combined with malicious retrieved data or an overly privileged agent.
That’s why signed artifacts should be combined with staged deployment, testing, canary releases, rollback capability, and runtime monitoring.
Provenance tells you what you deployed. It doesn’t tell you that what you deployed is good.
Eventually, Zero Trust reaches the GPU
This is where the discussion gets much more interesting.
The model doesn’t exist in isolation.
It runs in the container, operating system, drivers, firmware, host, and GPU.
Kubernetes provides the orchestration layer for many modern AI deployments, and the same security fundamentals apply: signed container images, admission controls, appropriate Kubernetes security policies, workload identities, and strong separation between workloads.
But GPU workloads introduce another layer of risk.
GPUs aren’t simply oversized CPUs. They have their own memory architectures, drivers, firmware, scheduling behavior, and hardware-specific attack surfaces.
A shared GPU environment can therefore introduce risks that don’t exist—or don’t look the same—in a conventional CPU workload.
For sensitive workloads, dedicated GPU nodes or validated hardware partitioning can reduce those risks. Error-Correcting Code (ECC) telemetry, GPU utilization, memory behavior, driver versions, and host state can also provide useful security signals.
For particularly sensitive workloads, confidential computing can provide another layer of protection.
A Trusted Execution Environment (TEE) is designed to protect workloads and data while they’re being processed. Confidential GPU infrastructure extends that concept into GPU-backed workloads and can provide additional attestation information about the environment.
That’s useful, not magic.
Confidential computing doesn’t make every hardware attack disappear, and it doesn’t eliminate every microarchitectural, firmware, or driver vulnerability. Research into GPU-specific attacks—including GPUHammer-style attacks—demonstrates why hardware isolation should be treated as one layer of defense rather than the entire security strategy.
The broader Zero Trust lesson is straightforward:
Don’t stop verifying at the application boundary.
Verify the environment that actually runs the application.
You can’t secure what you can’t see
Eventually, all of these controls come back to telemetry.
If an incident occurs, security teams need to know which model was running, where it was running, what data it retrieved, what tools the agent called, and what the underlying infrastructure looked like at the time.
That means AI environments need more than traditional application logs.
Useful signals include:
- Model version and cryptographic hashes
- Agent and tool-call traces
- Retrieval events and document identifiers
- Data provenance
- Host and workload attestation
- Driver and firmware state
- GPU errors and abnormal utilization
- Redacted inputs and outputs where appropriate
Those events can feed a Security Information and Event Management (SIEM) platform such as Microsoft Sentinel, along with other security telemetry.
The goal isn’t to log everything because logging everything sounds secure.
The goal is to make the attack path reconstructable.
If a model is compromised, can you identify every workload that ran that model?
If an agent token is stolen, can you determine which tools it accessed?
If a malicious document entered a RAG system, can you determine which responses used it?
If a GPU node shows abnormal behavior, can you identify which workloads were running there?
That’s the level of visibility Zero Trust for AI should be moving toward.
What this looks like in Azure
Azure provides a useful reference architecture because many of these capabilities already exist as cloud primitives.
Microsoft Entra ID can provide human and workload identity. Entra Workload Identity can extend that model into Kubernetes workloads and agents.
Azure Key Vault can broker access to secrets and cryptographic keys rather than leaving long-lived credentials embedded in applications.
Azure Kubernetes Service (AKS) can provide the orchestration layer, with dedicated GPU node pools, admission controls, signed container images, and workload identity mapping.
Private endpoints and virtual networks can isolate sensitive inference and retrieval infrastructure from unnecessary network exposure.
Azure Attestation and confidential-computing capabilities can provide additional evidence about workload and platform state for sensitive deployments.
Azure Monitor and Microsoft Sentinel can collect the resulting telemetry.
None of these services, individually, creates Zero Trust for AI.
That’s the wrong way to think about the architecture.
The services are enforcement and evidence mechanisms.
The actual architecture is the policy model connecting them.
A practical starting point
If I were implementing this incrementally, I wouldn’t try to build the entire thing at once.
I’d start here:
- Give every workload and agent its own identity. Avoid shared credentials and long-lived secrets.
- Control what agents can actually do. Don’t confuse permission to use a tool with permission to perform every operation that tool exposes.
- Treat RAG data as sensitive data. Secure the vector store, control retrieval, and maintain provenance.
- Establish model provenance. Sign approved model artifacts and maintain build and deployment records.
- Harden the runtime. Use signed containers, admission controls, workload isolation, and dedicated GPU infrastructure where the risk warrants it.
- Collect AI-specific telemetry. Know which model ran, what data it retrieved, what tools it called, and where it ran.
- Build toward richer authorization. Incorporate artifact integrity, runtime attestation, data sensitivity, and action context into policy decisions as the technology matures.
That’s a much more realistic starting point than trying to build some mythical “AI Zero Trust platform” in one shot.
What we still haven’t solved
There are some uncomfortable gaps.
Purpose-bound authorization is still immature. There isn’t a universal way to express and enforce complex statements about what an AI agent is allowed to accomplish.
Model provenance standards are still developing. SBOM-style approaches and signed artifacts are useful, but there isn’t one universally adopted model-provenance format that solves the problem.
GPU security is also an active area of research. Hardware attestation and confidential computing can reduce risk, but they don’t eliminate every hardware-level attack.
And perhaps the hardest problem is behavioral.
A model can be legitimately built, legitimately signed, legitimately deployed, and still contain a subtle backdoor or behave unexpectedly under a specific trigger.
We don’t have a magic attestation mechanism that proves an AI system will behave safely.
That means we’re back to a security principle that predates AI:
Defense in depth still wins.
The bigger Zero Trust question
If you already understand traditional Zero Trust, the important change isn’t that you need to throw away everything you’ve learned.
You don’t.
Strong identity still matters. Least privilege still matters. Segmentation still matters. Continuous monitoring still matters.
What changes is what you’re applying those principles to.
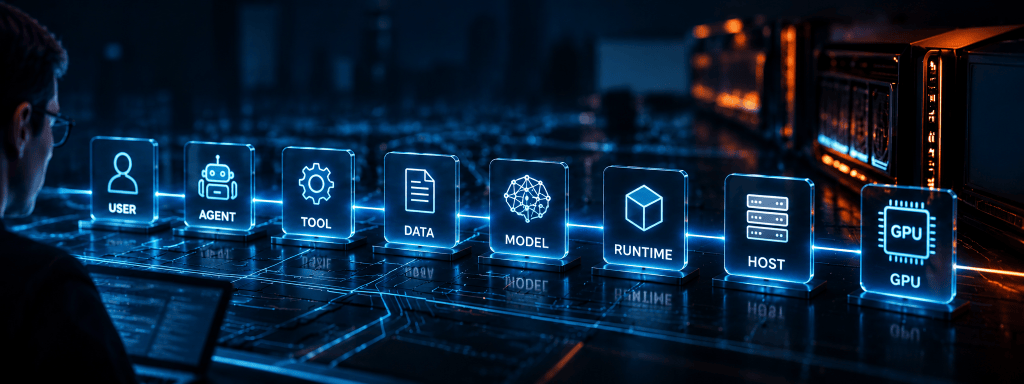
The trust boundary expands from:
User → Network → Application
toward:
User → Agent → Tool → Data → Model → Runtime → Host → GPU
At every step, we should be asking the same basic question:
What am I trusting, and what evidence do I have that I should trust it?
That’s the real challenge of Zero Trust for AI.
The human is still part of the security decision.
They’re just no longer the whole decision.